AI model size grew from millions of parameters in 2017 to trillions within 5 years[1]. Models that no longer fit in one accelerator or server distribute parameters, activations, and intermediate results across many devices. A single training step can therefore involve hundreds or thousands of accelerators and move terabytes of data among them.
Distributed training is not a collection of independent calculations joined only at the end. Accelerators exchange intermediate state, and the next step cannot begin until the slowest participant reaches the synchronization point. Adding more chips therefore increases both compute capacity and the number of places where latency or failure can stall the group. The fabric matters not only because it carries bytes, but because it determines how long the entire machine waits and how predictable its progress remains.
A review in Nature Reviews Electrical Engineering, written by teams at Panmnesia and Meta Infra, argues that the usual network vocabulary misses this point[1]. It asks whether a datacenter can inherit three properties that designers normally expect inside one chip: a common view of memory, a consistent transaction order, and bounded progress. We reconstructed that argument below, beginning with the comparison that gives the proposal practical meaning.
Not NVLink versus CXL, but two system architectures
This is not a link-level contest between NVLink and CXL. In current GB200 and GB300 NVL72 deployment architectures, NVLink and NVLink-C2C form a fast scale-up domain inside a rack, while the scale-out cluster interconnect between racks can use either Ethernet or InfiniBand[5]. RDMA traffic that leaves the local domain enters a NIC, a switched network, and software coordination. Address management, transaction order, and failure handling therefore cross an additional system boundary. The one-chip-like alternative places CPUs, accelerators, and memory in one hardware-managed CXL domain so that resources across system boundaries can follow shared addressing and transaction rules.
The orange path in Figure 1 is the important part of the comparison. NVLink remains the fast local connection inside each system. State that crosses to another system, however, enters a NIC and RDMA pipeline, an Ethernet or InfiniBand scale-out fabric, and software coordination across separate address, ordering, and failure domains. The cloud represents a network rather than one adjacent switch: a request can encounter routing decisions, several switch queues, and traffic-dependent waiting before it reaches the remote server. Those added stages place the review’s 256-byte round trip in the microsecond class and widen completion-time variation. This is why a synchronized job can wait at the network boundary even when every local NVLink hop is fast.
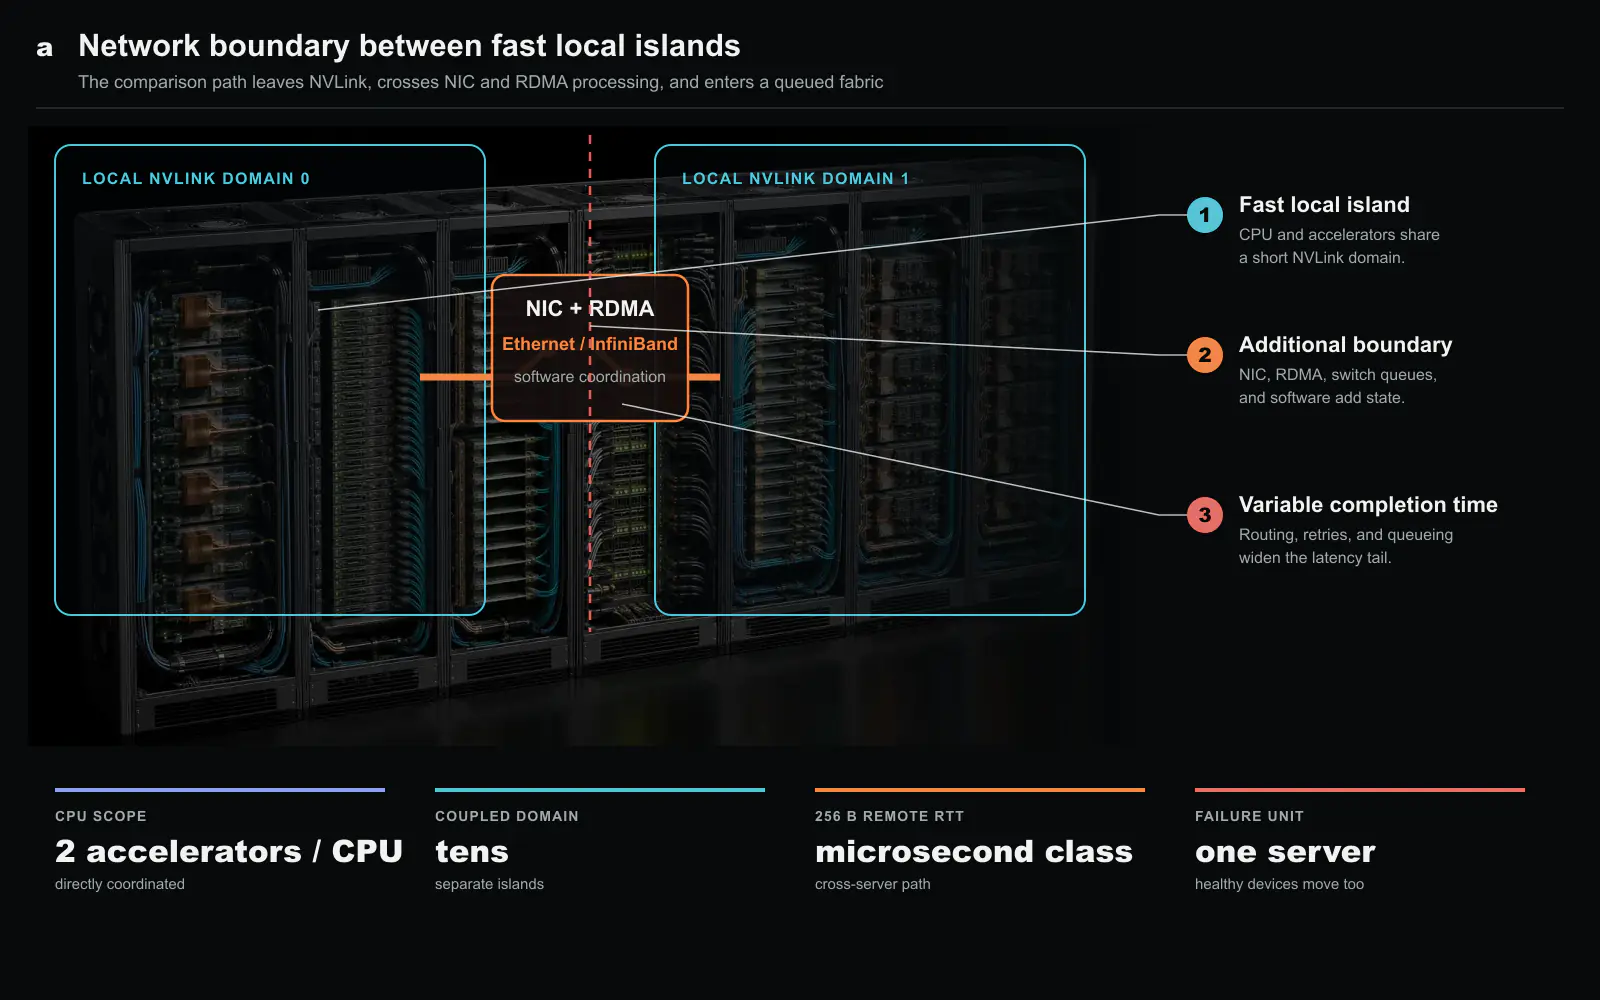
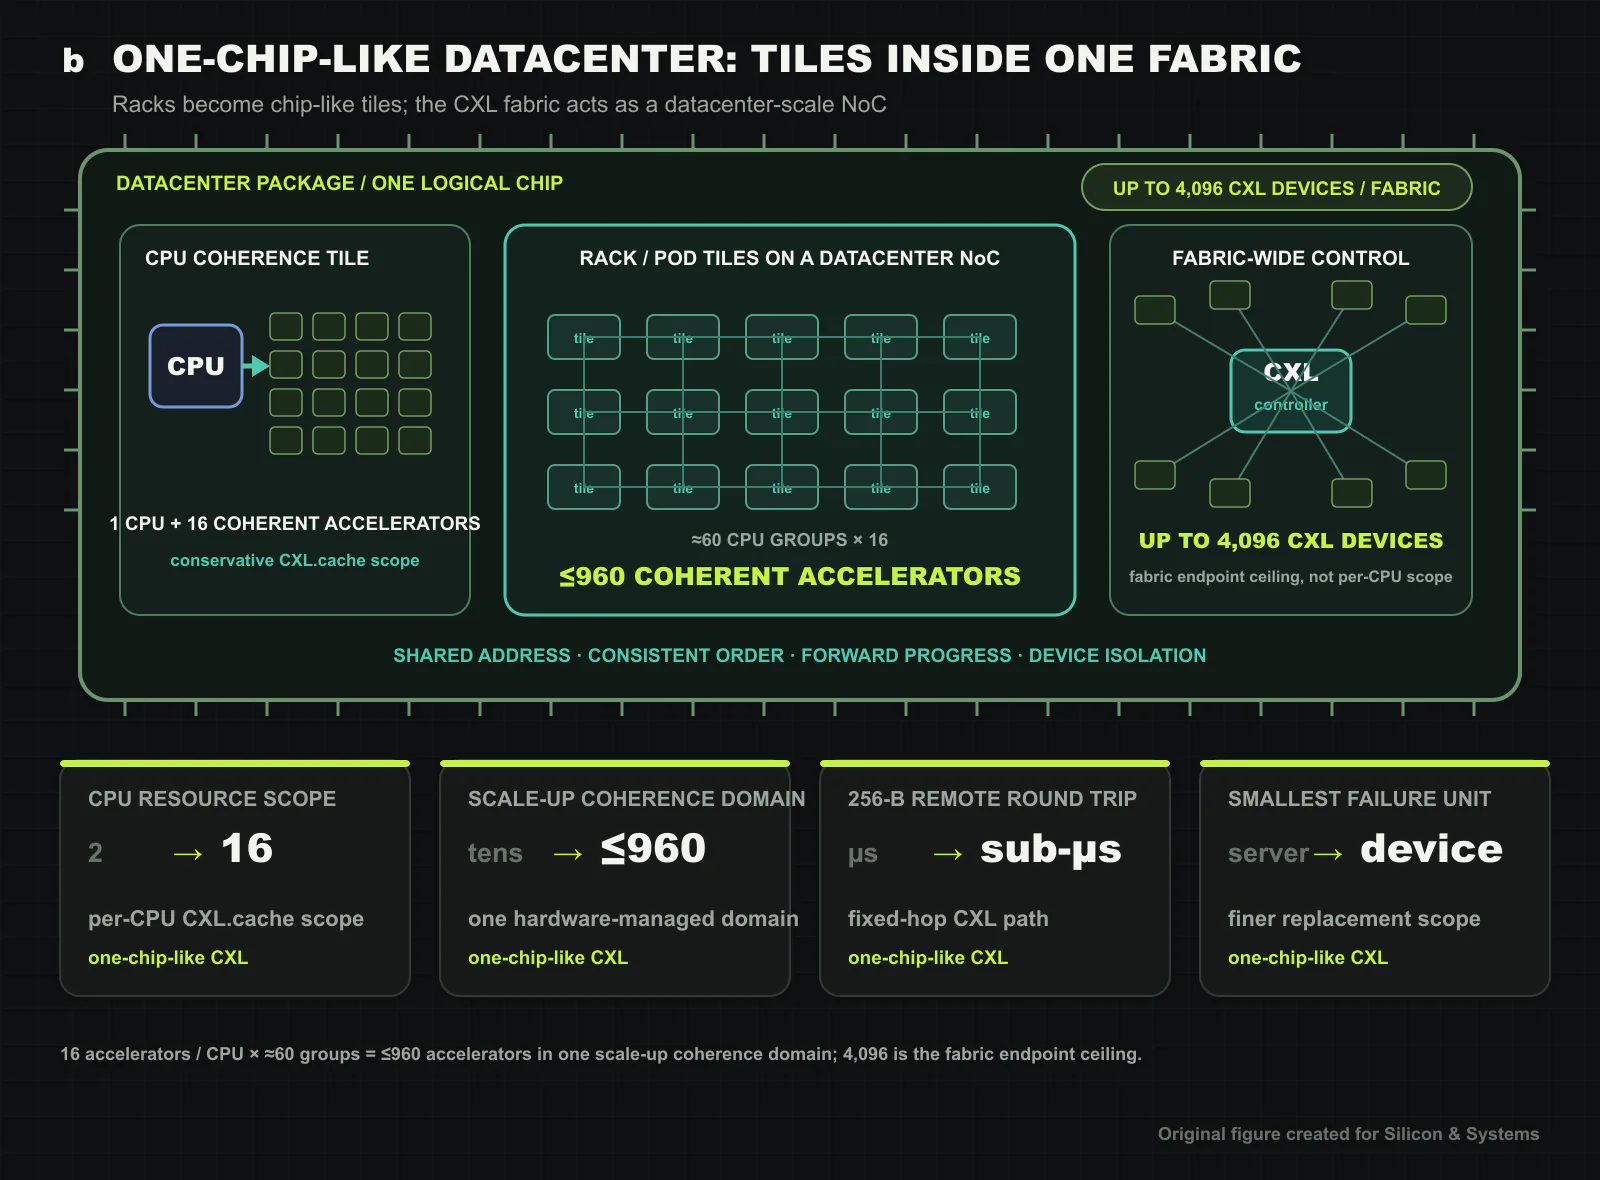
Figure 2 changes the visual model from separated servers to one logical chip. CPU groups become coherence tiles, racks and pods become larger tile arrays, and the CXL fabric takes the role of a datacenter-scale network-on-chip. A CPU tile contains 16 coherent accelerators under the review’s conservative CXL.cache assumption. When approximately 60 such groups share the same addressing and transaction-ordering rules instead of crossing separate scale-out RDMA domains, as many as 960 accelerators operate as one scale-up coherence domain. The outer fabric can span up to 4,096 CXL devices, but this is the fabric-wide endpoint ceiling rather than one CPU’s coherent accelerator count. The four lower cards retain the comparison axes from Figure 1, including the hundreds-of-nanoseconds access class and device-level replacement unit.
Four system-level advantages of the CXL design
One CPU directly manages more accelerators. One CPU in the reference configuration is paired with two accelerators. Under the review’s conservative CXL.cache assumption, one CPU can coordinate 16 in the same address space. This 8× wider management scope allows a larger unit of work to operate without crossing into network messaging and software coordination.
One scale-up coherence domain grows from tens of accelerators to as many as 960. Approximately 60 CPU groups, each coordinating 16 accelerators, share the same addressing and transaction-ordering rules across one CXL fabric. Because communication between groups no longer crosses a separate scale-out RDMA network stack, state that was managed independently in each server or local island moves under one hardware-enforced rule set. The gain is therefore coherence-domain density, not merely a larger device count. The review separately states that one fabric can span up to 4,096 CXL devices. The 960 value is the coherent scale-up scope, whereas 4,096 is the fabric-wide endpoint ceiling.
Cross-system access moves from microseconds to hundreds of nanoseconds. For a 256-byte device-to-device round trip, the path through an Ethernet- or InfiniBand-based RDMA fabric operates at microsecond scale, while a fixed-hop, hardware-regulated CXL path operates in the several-hundred-nanosecond class[1]. This advantage applies when an access would otherwise leave the local NVLink domain and traverse the network stack. It is not a claim that CXL is faster than a local NVLink hop.
A failed device can be replaced without retiring healthy resources. The proposed trays separate compute, memory, acceleration, and switching hardware, reducing the smallest replacement unit from a server to an individual device. Healthy components no longer have to leave service with the failed part, which can reduce stranded capacity and operational disruption. CXL hot-plug and runtime reconfiguration provide the hardware path, while uninterrupted workload recovery still requires system software and an appropriate recovery policy.
The four comparison lines describe different consequences of one structural change. Direct CPU scope grows from 2 to 16 accelerators, and approximately 60 CPU groups combine into one scale-up coherence domain of as many as 960 accelerators. Remote access leaves the scale-out RDMA network stack for a fixed-hop hardware path, while the failure unit shrinks from a server to a device. Shared addressing, fixed hop counts, consistent ordering, and device-level disaggregation therefore change scale, access time, and recovery scope together.
Why bandwidth is not the whole problem
Inside a chip, wire length, pipeline depth, and arbitration are designed together. Delay still exists, but its range is narrow enough that other blocks can plan around it. A datacenter transfer crosses cables, adapters, switch queues, protocol handlers, and runtime code. Each layer adds state-dependent delay. Production network measurements show a heavy tail, with the 99th percentile near 5× the median[4].
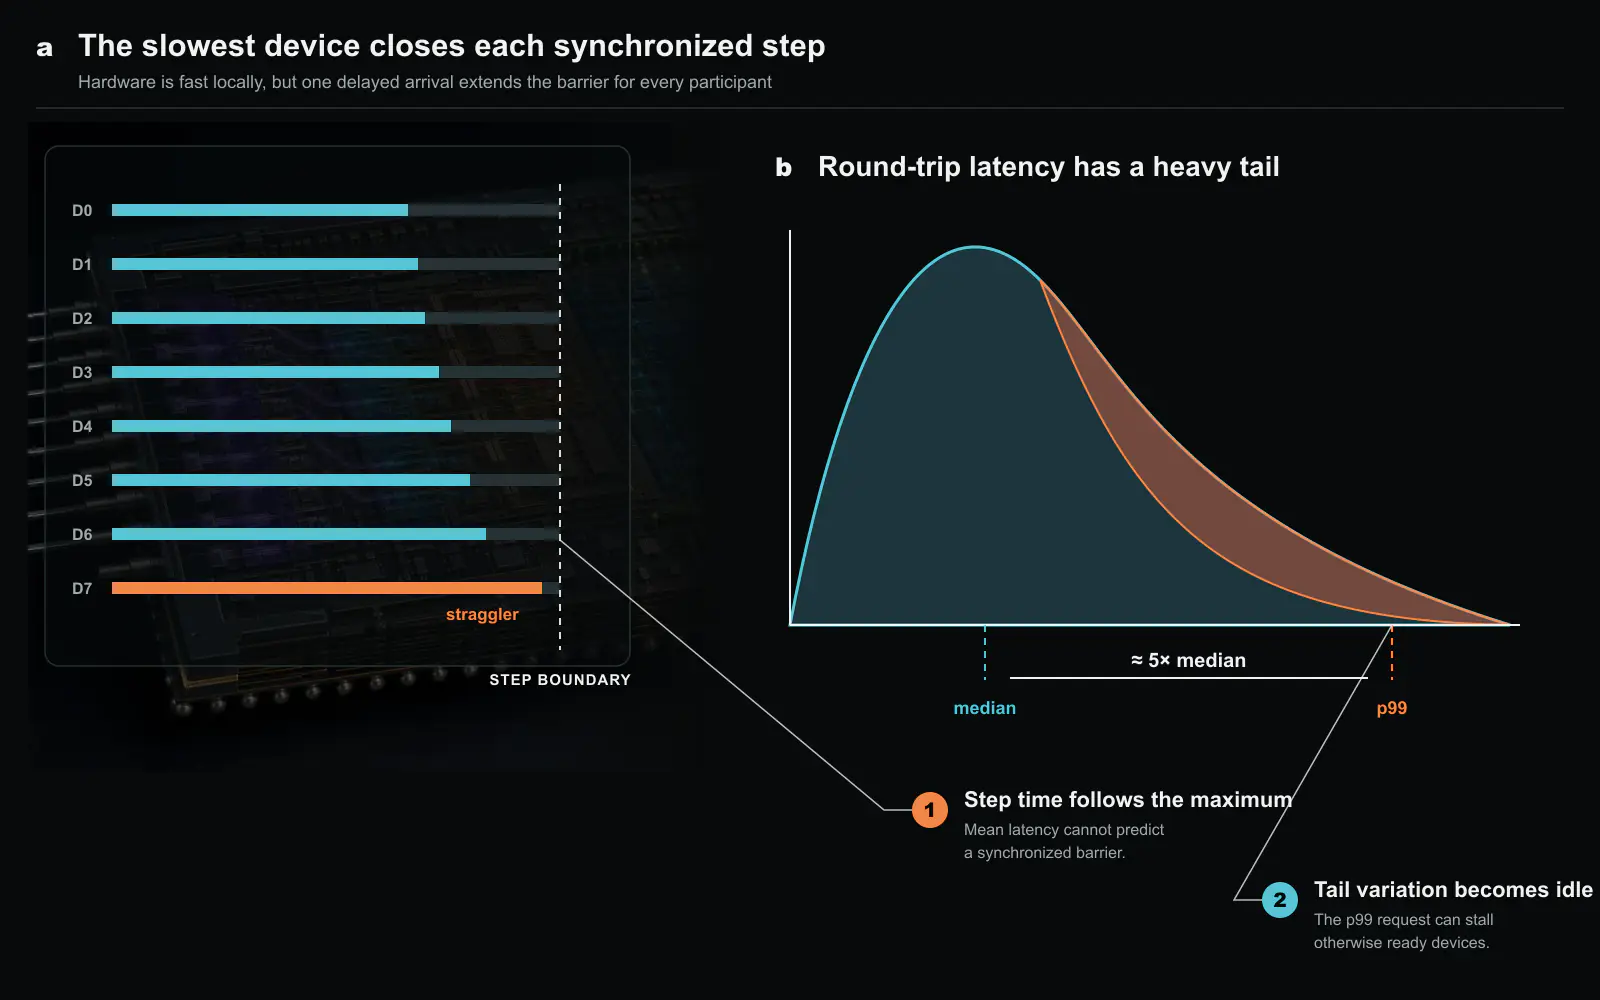
A 400 Gbit/s link shortens serialization time but does not make queue occupancy, software scheduling, or path length uniform. This distinction matters at a barrier. Seven accelerators can finish early and contribute no further progress while the eighth is delayed. The lost time is the pale region in the left panel, not an idle link that a higher headline bandwidth automatically fills.
The failure model follows the same collective structure. A request service can route around one slow host and lose only a fraction of capacity. A synchronized training group often has to restart from a common checkpoint when one member stops. The relevant availability question is therefore whether the group advances predictably, not simply how many servers remain powered on.
Scale does not preserve per-device efficiency automatically. One large-scale AI system cited by the review saw efficiency per device fall to the mid-80% range when the participant count increased sixfold[1]. Dependencies and synchronization time grew along with the available compute. For such workloads, tail latency, the cost of maintaining shared state, and the recovery scope after a fault can limit scaling more directly than headline bandwidth.
What CXL changes, and what it does not
Disaggregation originally solved a utilization problem. Separating CPU, memory, storage, and accelerators lets each resource scale and refresh on its own schedule, avoiding fixed server configurations that can leave more than half of some resources unused. That model works when machines are mostly independent. AI training breaks the assumption because every step repeatedly touches state produced elsewhere.
A shared address space needs a concrete explanation. In a network-based system, software identifies a buffer on another machine, issues a communication request, copies the data, and signals that the copy has completed. With shared addressing, multiple devices use the same address to refer to the same data location. Cache coherence supplies the companion rule: after accelerator A updates a value, accelerator B must observe the current value rather than a stale copy. Shared addressing without coherence can leave two devices reading different data from what appears to be the same location.
CXL changes remote access from a network-message destination into part of the memory hierarchy. CXL.io preserves the PCIe path for discovery and I/O. CXL.cache allows an accelerator to participate in the host coherence domain, while CXL.mem exposes device-attached memory through load and store operations. Their combinations define a cache-coherent accelerator without local memory (Type 1), an accelerator with local memory (Type 2), and a memory expansion device (Type 3). The classification originated in server attachment. A one-chip-like design instead treats these devices as recomposable compute and memory blocks of a larger fabric.
The revisions of CXL progressively widened that scope. CXL 1.0 enabled hardware-managed access between a CPU and devices outside its package. CXL 2.0 added switching so that several devices could join one domain. CXL 3.0 introduced fabric-attached memory, direct device-to-device transfers, and a unified address space for operation beyond one server. CXL 4.0 raises the physical lane rate to 128 GT/s, supports channels with as many as four retimers, and allows several physical ports to operate as one logical port[2].
Coherence tracking also changed to support scale. Instead of maintaining one fabric-wide central table, devices distribute state and metadata according to the address ranges they manage. This organization reduces the tendency for coherence bookkeeping to grow in direct proportion to the entire system. The review cites prior implementations of directory coherence, snoop filtering, and state forwarding across devices that improved performance by more than 25% over software-managed coherence[1]. The result shows why moving coherence work from software coordination into a fixed hardware path directly improves performance as the fabric grows.
Those standards provide semantics, but they do not guarantee one-chip-like timing. Fan-out, buffering, routing depth, and per-hop processing remain implementation choices. A compliant component can put critical work in firmware or in a fixed hardware pipeline, and those two designs can have different latency spreads. Likewise, mesh, torus, and dragonfly topologies maximize useful connectivity but do not automatically give every pair the same hop count. The review’s real proposal begins where the CXL specification stops.
The fabric therefore needs three execution rules in addition to shared data. Ordering determines which of several updates to the same state takes effect first. Visibility determines when one device can observe another device’s update. Forward progress ensures that requests eventually complete instead of waiting indefinitely on one another. A memory controller and network-on-chip enforce these properties inside a die. The one-chip-like fabric must extend the same responsibilities across switches and racks.
Three hardware blocks make the difference
A non-blocking switch with high fan-out connects many devices at one stage and therefore limits the number of hops between them. Low fan-out forces the fabric to add switch levels as it grows, increasing latency and the number of possible routes. A non-blocking design provisions internal capacity so that simultaneous inputs do not oversubscribe the available outputs. Matching the forwarding pipeline and electrical distance at every port then bounds variation among paths. All-reduce, parameter exchange, and activation traffic need this property because they arrive concurrently rather than as isolated flows.
The link acceleration unit (LAU) moves repeated protocol work into a fixed pipeline. At the fabric boundary, a request must translate local addressing and metadata into a fabric space as large as 4 PB. The pipeline then distinguishes 8 CXL.io, 6 CXL.cache, and 12 CXL.mem transaction types, selects an egress port, and handles retries and congestion[1]. Firmware can implement the same semantics, but its service time moves with control activity and event processing. Common management interfaces expose more than one hundred operations plus dozens of event-log categories, so the scheduling variability is not hypothetical.
The LAU puts address translation, header processing, transaction management, and forwarding decisions on a fixed fast path. It also monitors link state and can adjust retry windows, queue admission, and congestion indicators. For example, CXL defines default egress-occupancy values of 10% and 25% for moderate and severe congestion, respectively, while an implementation can tune transport behavior around them[1]. The goal is not constant latency under every load. It is to limit how often retries and transient queues expand into tail latency.
The fabric controller gives distributed ports one basis for priority and order. It decomposes transaction messages into physical transfer units and reassembles them while performing integrity, retry, sequence, and ordering checks. CXL can address as many as 4,096 devices in a fabric, at which point correct device-local behavior is not sufficient. If ports apply different priorities, the same request can be ordered differently under contention, and possible policy interactions grow combinatorially with controller count. Applying one policy across controllers does for the fabric what a transaction engine does inside a system-on-chip: it limits behavioral combinations that software would otherwise have to reconcile.
This division does not hardwire every control decision. Hardware owns the fast path that directly determines the latency of each transfer, while software retains exception handling, device management, and policy updates. The objective is to remove variable scheduling from the critical path rather than to remove software from the system.
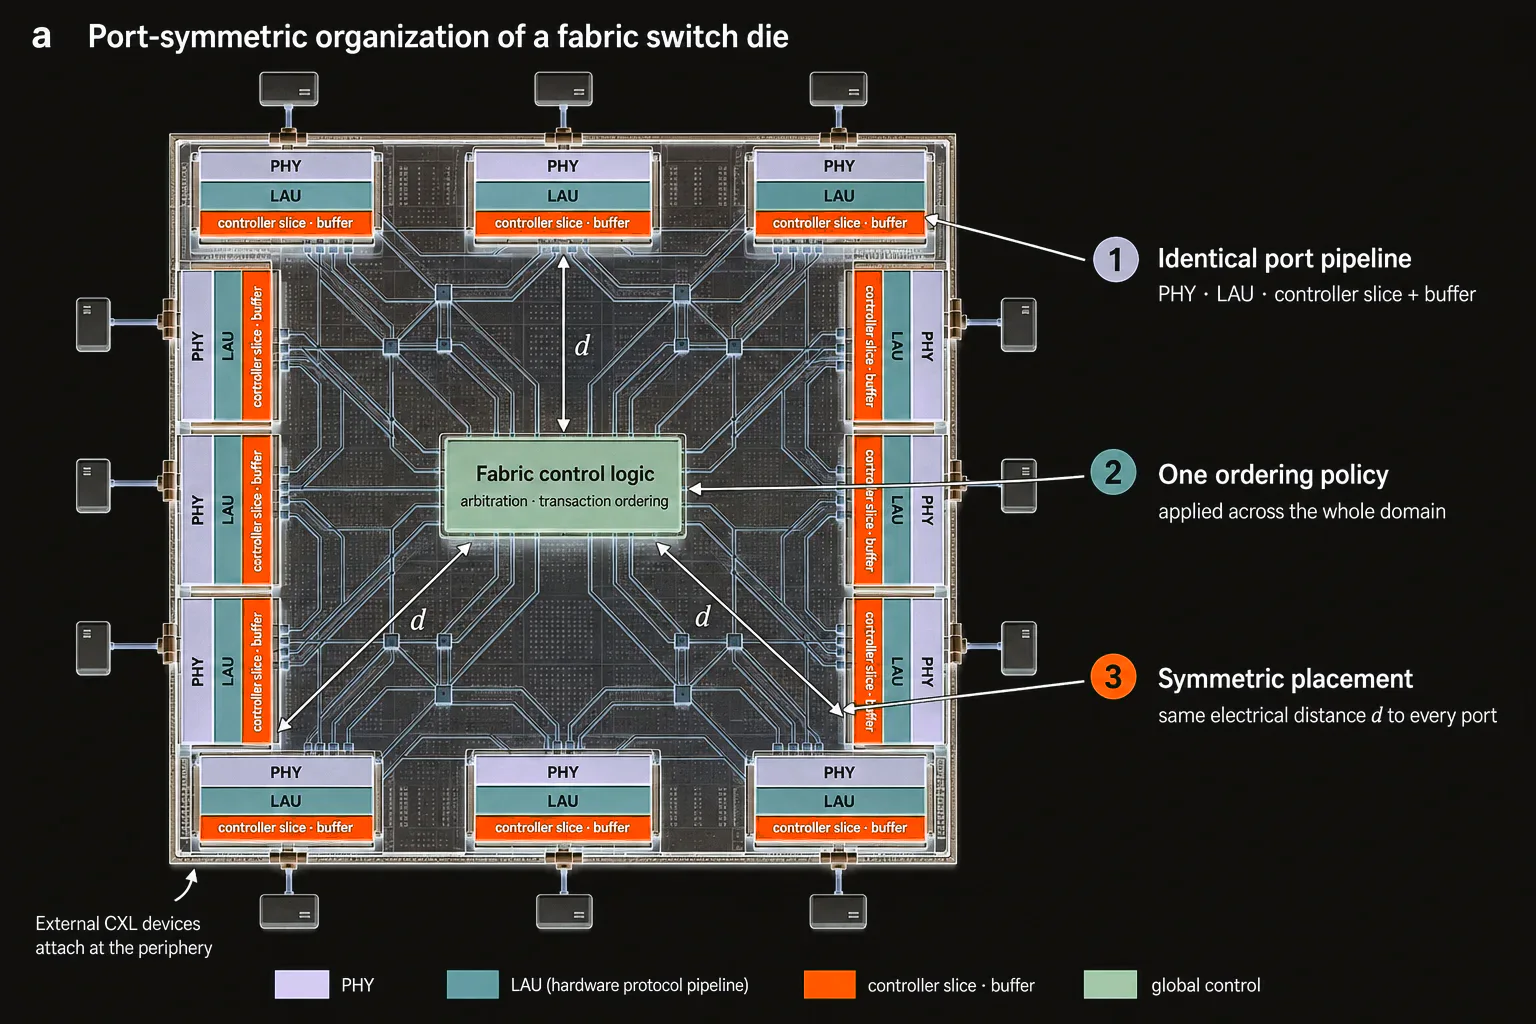
The floorplan makes the requirement tangible. Identical port pipelines sit around a central control block, while a crossbar or multistage network supplies the internal paths. A larger switch must preserve those common pipelines and arbitration rules as its port count grows. Otherwise, differences inside the switch reintroduce the latency variation that the fabric is intended to reduce. Thus, the LAU and controller requirements also determine how the next-level tray topology can scale.
From trays to one fabric
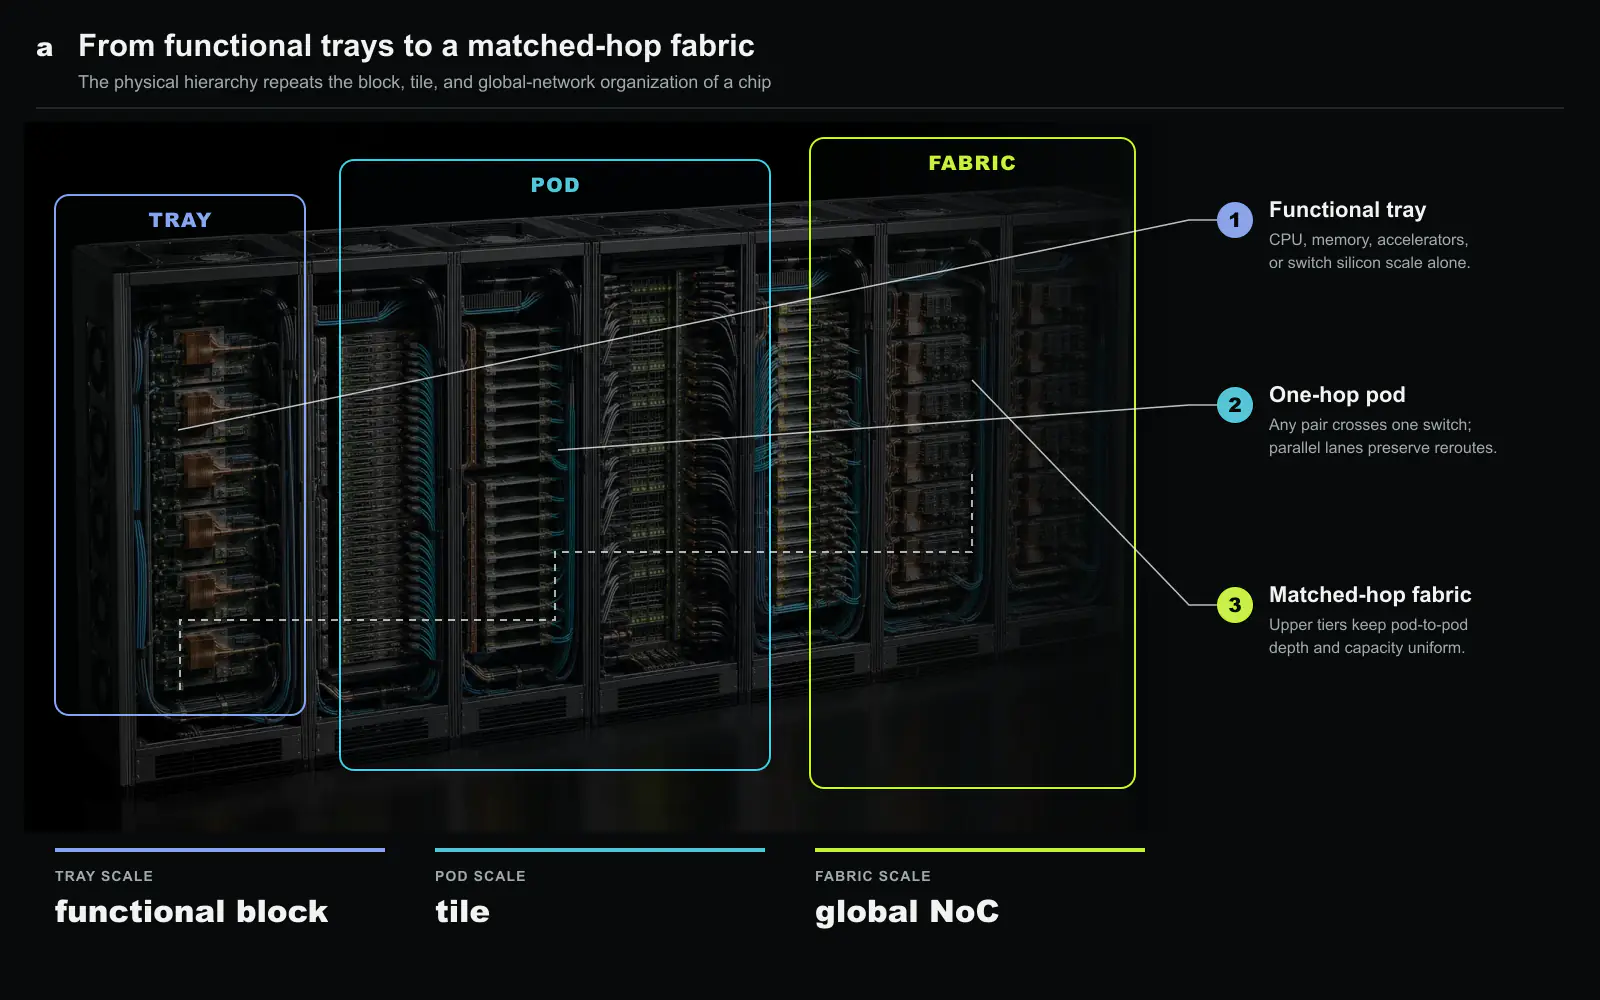
The deployment hierarchy repeats the same rule at three scales. A tray packages one resource type and exposes CXL links. Since CPU, memory, and acceleration no longer have to share one fixed enclosure, the operator can add a constrained resource or service the tray containing a failed device without replacing a complete server configuration.
A pod connects trays so that any pair communicates through one switch stage. Equivalent parallel lanes preserve the same hop count when traffic is rerouted around a failed path. The upper fabric connects pods with matched traversal depth. It can use a multistage Clos or fat-tree, while mesh, torus, and ring options remain possible if they preserve the latency bound. A pod switch may accept limited oversubscription to attach more trays, but upper-tier switches remain non-oversubscribed so that pod-to-pod bandwidth and traversal behavior stay uniform.
Coherence follows the physical hierarchy. The pod switch becomes the local ordering point for requests, responses, and snoops. Upper-tier switches extend the order between pods while matching the distance traversed by coherence traffic. Ordering here does not mean forcing unrelated memory operations through one serial queue. It means that two updates competing for the same state eventually meet a stable decision point and receive an order that every participant can interpret in the same way.
Visibility is the companion rule. A shared address is useful only if a reader can determine whether its cached value remains current. Directory state, snoop filtering, and coherence messages narrow that work to the devices that may hold a copy instead of broadcasting every update to the entire fabric. Forward progress completes the contract: separate request, response, and data channels combine with credit-based flow control and predefined deadlock-free routes. None of these mechanisms eliminates congestion; together they make its handling a hardware rule rather than a software timing accident.
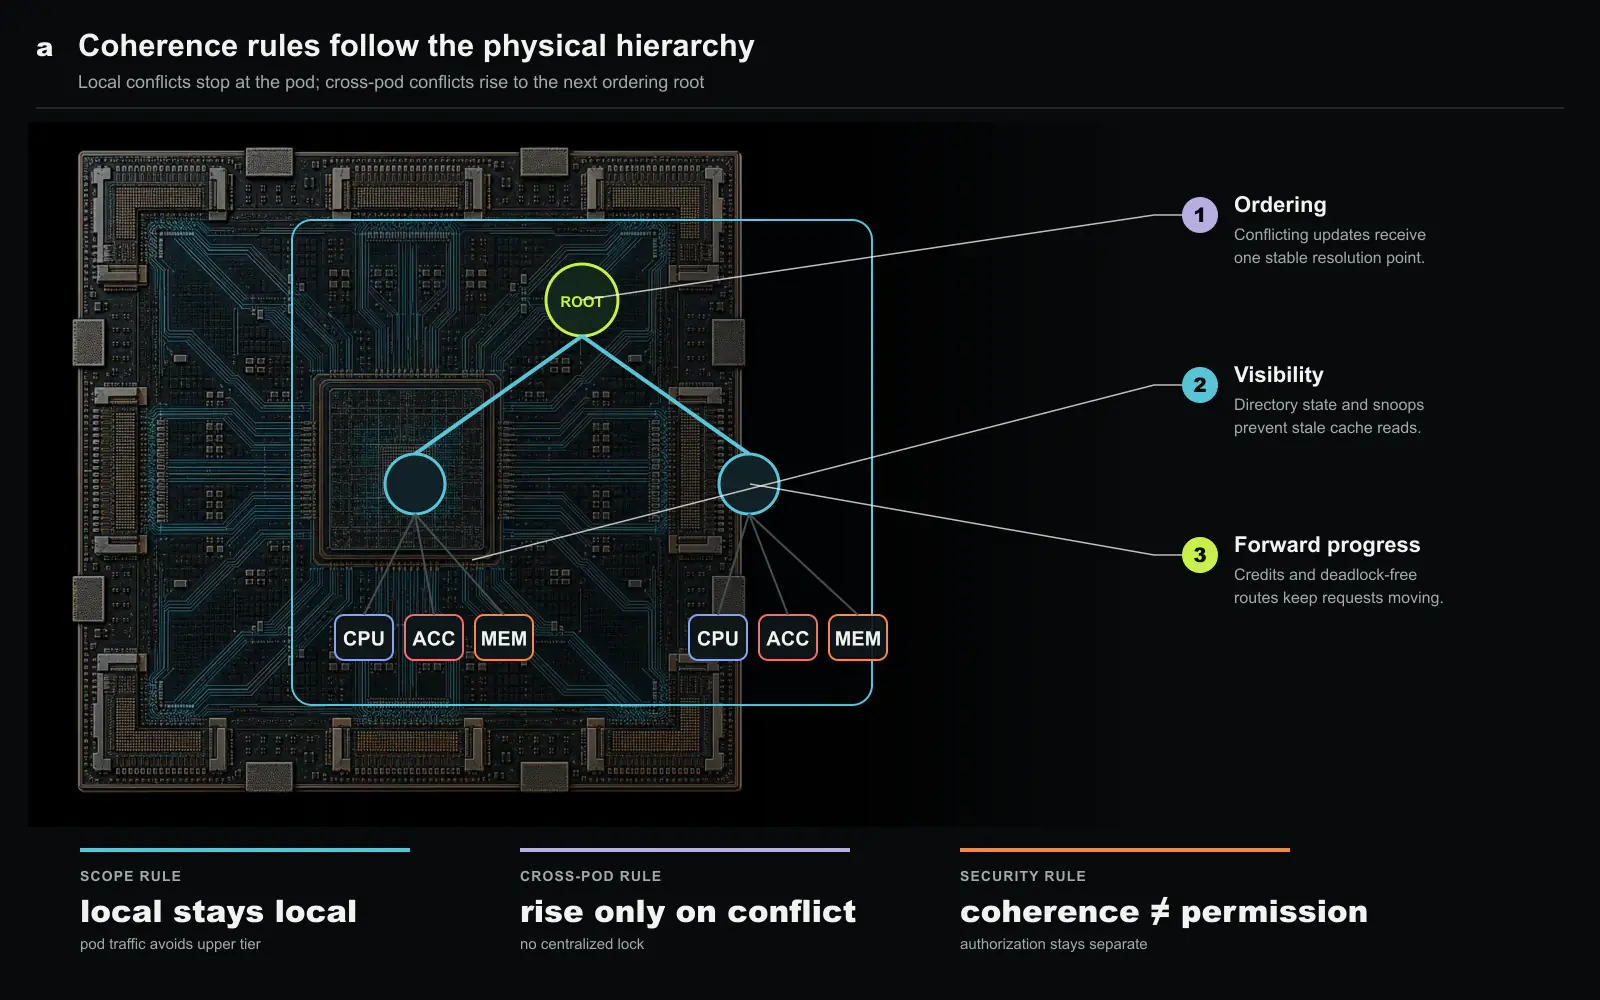
The hierarchy also limits the scope of each decision. Transactions within a pod need not visit the upper tier, while cross-pod conflicts rise to the next ordering root. This locality is what keeps a global coherence domain from behaving like one centralized lock. It also explains why coherence and authorization must remain separate: hardware can maintain a current value across the domain without granting every tenant permission to read or modify it.
This is the bridge between the diagram and the evaluation. Sixteen accelerators per CPU require a shared address and control scope. Hundreds of nanoseconds require a short, fixed pipeline. Device-level replacement requires resource boundaries that are no longer identical to server boundaries. The four results are consequences of the structure, not independent feature claims.
The physical boundary is part of the architecture
The electrical fabric is not unlimited. At 128 GT/s, loss and jitter restrict each copper segment to a few meters. Two retimers can extend the stated reach to about 7 m, enough for roughly six or seven standard racks. Beyond that span, CXL-over-optics, optical backplanes, or co-packaged optics become necessary. Optics can extend reach, but it does not solve ordering, cooling, validation, or cost.
The 7 m figure should therefore be read as a deployment envelope, not as a universal cable guarantee. Connector loss, trace length, retimer placement, temperature, and the required signal margin all spend the same physical budget. Two layouts with the same rack count can expose different path variation, so the fabric cannot promise chip-like timing from protocol semantics alone.
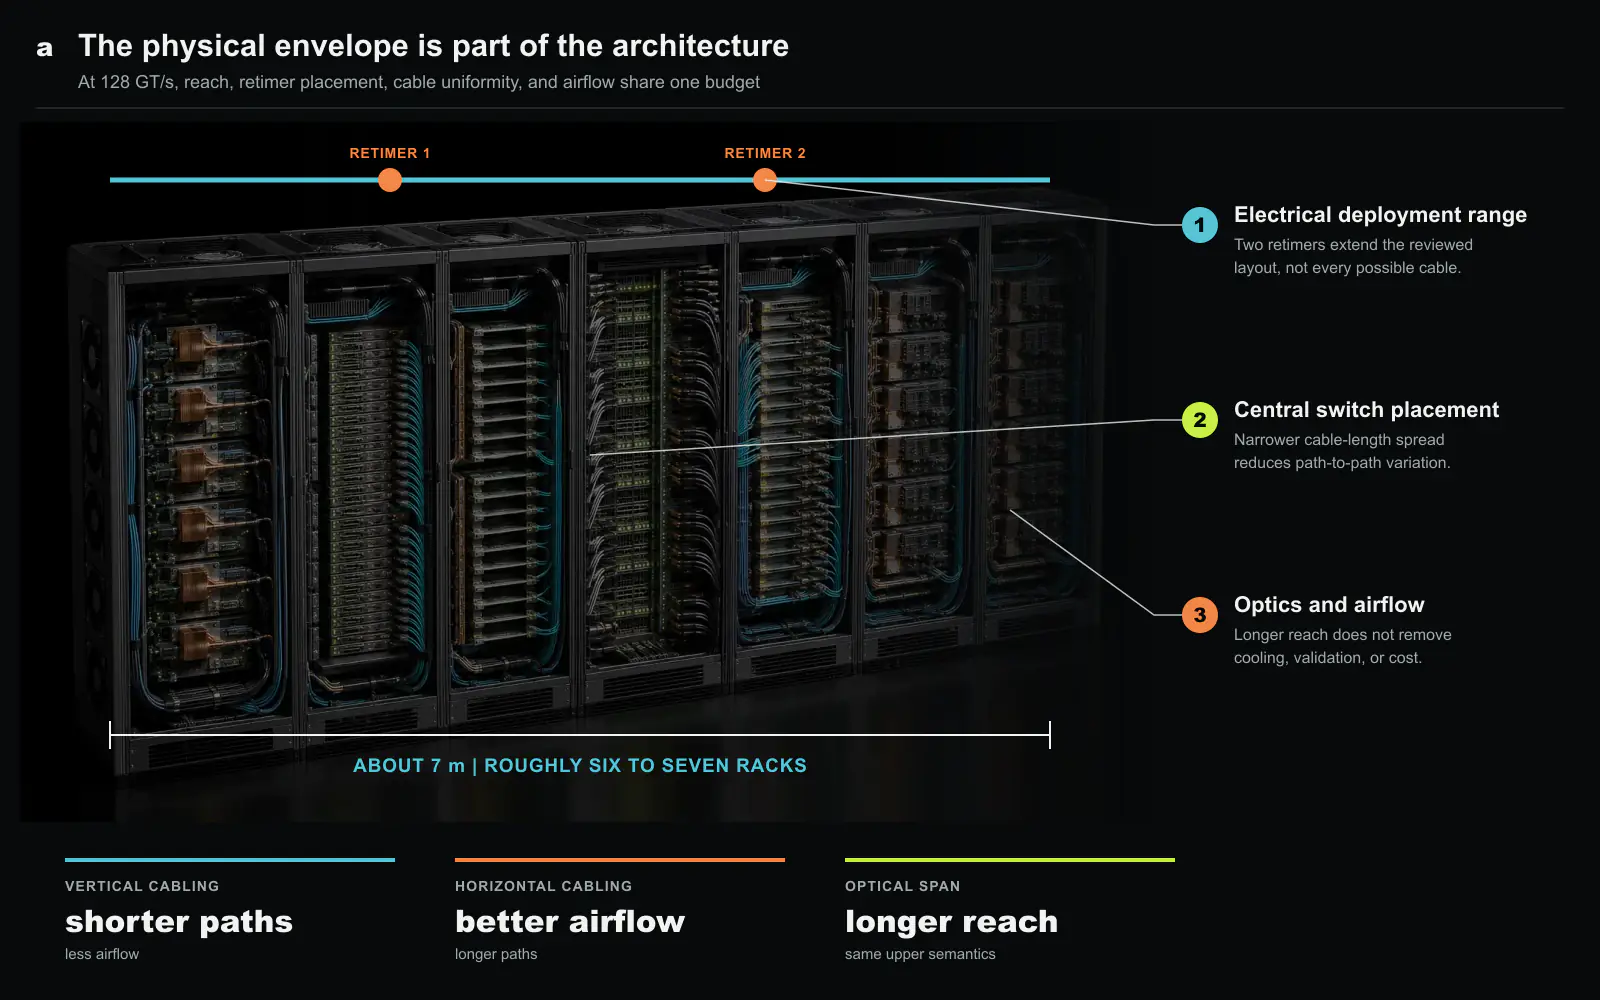
Rack layout also changes timing. Vertical cabling shortens paths but obstructs airflow; horizontal routing improves airflow at the cost of distance. Placing switch trays near the rack center narrows the cable-length distribution. Accelerator and CPU trays add heat, memory trays consume routing area, and temperature drift can return as signal variation. In this design, mechanical placement is part of the latency architecture.
A shared fabric also enlarges the security consequence of a configuration error. Multi-tenant deployment needs explicit isolation domains, hardware access checks at devices and switches, and CXL Integrity and Data Encryption below them. Coherence should never imply permission. Hot-plug likewise needs authorization, attestation, and recovery policy above the electrical mechanism.
Optics will probably enter in stages rather than replace the electrical fabric at once. CXL-over-optics can extend physical reach while retaining the address and ordering semantics of the upper protocol layers. Adoption nevertheless depends on link density, packaging, qualification, supply-chain readiness, operational tools, and total cost of ownership in addition to optical-device performance. A practical early configuration can retain copper inside racks and introduce optics on longer rack-to-rack spans. Such mixed fabrics also require automated monitoring, validation, and reconfiguration across the whole domain.
Our read: a rare architecture review sets a system agenda
The venue is part of this paper’s significance. Nature Reviews Electrical Engineering commissions its Reviews to synthesize a field and define its important research directions[6]. Nature Portfolio covers computing broadly, but its own Computing collection is weighted toward devices, emerging computing methods, AI applications, and their societal implications. Articles centered on cache coherence, switch microarchitecture, and rack-scale system design appear only sparingly[7]. A peer-reviewed Review devoted to datacenter computer architecture is therefore an unusual opportunity to place chip design, fabric control, packaging, rack layout, cooling, reliability, and operations inside one engineering argument.
The Meta Infra collaboration is similarly uncommon. Meta’s public AI research index spans almost two thousand publications and is organized primarily around machine-learning and specialist conference venues; Nature-branded journals appear as exceptional rather than routine outlets in that record[8]. This Review brings infrastructure architecture into that select class. More importantly, it joins an operator’s requirements with Panmnesia’s CXL controller and link-acceleration silicon work, so the proposal is framed across deployment constraints and implementable hardware rather than as a protocol feature list.
The paper is most persuasive when it changes the basis of the NVLink plus scale-out network comparison. The issue is not that any of these technologies is slow. NVLink provides a tightly controlled local domain, while Ethernet or InfiniBand scales communication among such domains. A structural boundary remains when one workload requires common addressing, transaction ordering, and failure handling across both. The proposed CXL scale-up fabric moves those responsibilities into one hardware-managed system.
Its headline values define how far the system boundary moves. The stated CXL.cache assumption expands direct CPU management from 2 to 16 accelerators, an 8× increase. Approximately 60 such groups then share addressing and transaction order across one scale-up coherence domain of as many as 960 accelerators without traversing a separate scale-out RDMA network domain. The separate 4,096-device limit is the addressable ceiling of one CXL fabric, while the fixed-hop hardware path reaches the hundreds-of-nanoseconds access class. Together, these values align switch, silicon, rack, and software design around a datacenter-scale system bus instead of a network of separately managed servers.
For system builders, four concerns now belong in one design exercise: useful training throughput under tail load, coherence traffic across hundreds of accelerators, recovery after removing a device during a job, and power plus cabling cost across six or seven racks. Treating them together turns “one chip” into an architecture criterion for predictable performance, bounded recovery, and cost-aware scaling.
Source and copyright note
This article is an editorial digest written by Silicon & Systems. It restates the review’s ideas and reported values in our own language. No sentence, figure, table layout, or glossary entry from the published version has been reproduced. Every figure was created independently for this article. The version of record, including the complete figures and bibliography, is available through DOI 10.1038/s44287-026-00315-5. Copyright (c) Springer Nature Limited 2026.